Wednesday, October 11, 2017

Scaling of urban phenomena


Via Jason Potts, I came across an interesting Nature article [1] on the scaling of urban phenomena. In particular, the authors propose to explain the relationships in the graphic above.

Now the paper goes much further (explaining variance and the scaling exponents themselves) than I will, but I immediately noticed these relationships are all information equilibrium relationships ⇄ N with information transfer indices β:

log Y/Y₀ = β log N/N₀

The reasoning behind this relationship is that the information entropy of the state space (opportunity set) of each phenomena (Y) is in equilibrium with the information entropy of the population (N) state space. This falls under deriving the scaling from the relationship of surfaces to volumes mentioned in the paper (you can think of the information content of a state space as proportional to its volume if states are uniformly distributed, and the IT index measures the relative effective dimension of those two state spaces).

I wonder if adding shocks to the dynamic equilibrium rate (d/dt log Y/N) handles some of the deviations from the linear fit. For example, the slope of the upper left graph should actually relate to the employment population ratio — but as we know there was a significant shock to that ratio in the 70s (due to women entering the workforce). I can't seem to find employment population ratio data at the city level. There is some coarse data where I can get employed in e.g. Seattle divided by King county population as a rough proxy. We can see at the link there's a significant effect due to shocks (e.g. the recessions and the tail end of women entering the workforce). The model the authors use would imply that this graph should have a constant slope. However, the dynamic equilibrium model says that it has constant slope interrupted by non-equilibrium shocks (which would result in data off of the linear fit).

But this paper is interesting, especially in its description of an underlying model — a place where the information equilibrium approach is agnostic.

...

Footnotes:

[1] The article itself is oddly written. I imagine it is due to the house styles of Nature and Harvard, but being concise does not seem to be a primary concern. For example, this paragraph:
The central assumption of our framework is that any phenomenon depends on a number of complementary factors that must come together for it to occur. More complex phenomena are those that require, on average, more complementary factors to be simultaneously present. This assumption is the conceptual basis for the theory of economic complexity.
could easily be cut in half:
The central assumption of our framework is that phenomena depend on multiple simultaneous factors. This assumption is behind economic complexity theory.
Another example:
We observe scaling in the sense that the counts of people engaged in (or suffering from) each phenomenon scale as a power of population size. This relation takes the form E{Y|N} = Y₀ N^β, where E{⋅|N} is the expectation operator conditional on population size N, Y is the random variable representing the ‘output’ of a phenomenon in a city, Y₀ is a measure of general prevalence of the activity in the country and β is the scaling exponent, that is, the relative rate of change of Y with respect to N.
could also be cut in half:
The number of people experiencing each phenomenon is observed to scale as a function of population size E{Y|N} = Y₀ N^β, where E{⋅|N} is the expectation operator conditional on population size N, Y is the number of people experiencing a phenomenon in a city with scale parameter Y₀ and β, the scaling exponent.
I could even go a bit further:
The number of people experiencing each phenomenon is observed to scale as a function of population size Y ~ N^β, where N is the population size, Y is the number of people experiencing a phenomenon in a city, and β is the scaling exponent.

Dynamic equilibrium: US prime age population

There was a tweet saying that the US prime age population (25-54) hadn't increased in a decade. I decided to get a handle on the context in terms of the dynamic equilibrium model:


It's true this population measure hasn't increased in a decade, but that is more a measure of the size of the shock due to the recession (leading to e.g. reduced immigration) than anything special about today. In fact, the growth rate today is consistent with twenty-first century prime age population growth.

JOLTS leading indicators update

The August 2017 JOLTS numbers are out (July numbers comparison is here), and the hires series is continuing a correlated deviation from the dynamic equilibrium:


There's still insufficient data to declare a shock, and the best fit results in only a small shock [1]:


...

Footnotes:

[1] The evolution of the shock counterfactual is relatively stable:


Saturday, October 7, 2017

Compressed sensing and the information bottleneck

For those that don't know, my day job is actually in signal processing research and development in the aerospace sector. As I document in my book, I came by economics research via a circuitous route. One subject I worked on for awhile (and still do to some extent) is called compressed sensing (Igor Carron's blog is a great way to keep up with the state of the art in that field, and his Google site provides a nice introduction to the subject).

One of the best parts about Igor's blog is that he brings together several lines of research from machine learning, matrix factorization, compressed sensing, and other fields and frequently finds connections between them (they sometimes appear in his regular feature "Sunday Morning Insight").

In that spirit — although more of  a Saturday Afternoon Insight — I thought I'd put a thought out there. I've been looking at how the price mechanism relates to the information bottleneck (here, here), but I've also mused about a possible connection between the price mechanism and compressed sensing. I think now there might be a connection between compressed sensing and the information bottleneck.


In compressed sensing, you are trying to measure a sparse signal (a signal that appears in only a sparse subset of your space x, like a point of light in a dark image or a single tone in a wide bandwidth). To do so, you set up your system to make measurements in what is called the dense domain — through some mechanism (Fourier transform, random linear combinations, labeled with Φ) you make the variable you wish to measure appear throughout the space y. Therefore a few random samples of the entire dense space give you information about your sparse signal, whereas a few random samples of an image with a single bright point would likely only return dark pixels with no information about the point.


Is this how the information bottleneck works? We have some domain X in which our signal is just a small part (the set of all images vs the set of images of cats), and we train a feedforward deep neural network (DNN, h1 h2 → ... hm) that creates a new domain Y where our signal information is dense (cat or no cat). Every sample of that domain tells us information about whether there is an image of a cat being fed into the DNN (i.e. if it identifies cats and dogs, a result of dog tells us it's not a cat).

In compressed sensing, we usually know the some properties about the signal that allow us to construct the dense domain (sparse images of points can be made dense by taking a 2D Fourier transform). However, random linear combinations can frequently function as a way to make your signal dense in your domain. In training a DNN, are we effectively constructing a useful random projection of the data in the sparse domain? As we push through the information bottleneck, are we compressing the relevant information into a dense domain?

The connection between compressed sensing and the structure of a neural net has been noted before (see e.g. here or here), the new part (for me at least) is the recognition of the information bottleneck as a useful tool to understand compressed sensing — "opening the black box" of compressed sensing.

...

Update 19 May 2019

This might also be connected:
Matrices of (approximate) low rank are pervasive in data science, appearing in recommender systems, movie preferences, topic models, medical records, and genomics. While there is a vast literature on how to exploit low rank structure in these datasets, there is less attention on explaining why the low rank structure appears in the first place. Here, we explain the effectiveness of low rank models in data science by considering a simple generative model for these matrices: we suppose that each row or column is associated to a (possibly high dimensional) bounded latent variable, and entries of the matrix are generated by applying a piecewise analytic function to these latent variables. These matrices are in general full rank. However, we show that we can approximate every entry of an m×n matrix drawn from this model to within a fixed absolute error by a low rank matrix whose rank grows as O(log(m+n)). Hence any sufficiently large matrix from such a latent variable model can be approximated, up to a small entrywise error, by a low rank matrix.
Paper link on arXiv — almost all large enough matrices are effectively low rank.

Friday, October 6, 2017

(Prime age) civilian labor force participation data

In addition to the unemployment rate, there is also new data for the prime age civilian labor force participation rate which we can use to track the performance of our forecast (last updated here):


Latest unemployment data

New unemployment data is out, so it's time to check to see how the forecasts are doing compared to reality. First, I want to throw out two forecasts as rejected: one from me, and one from the FRBSF. I started putting them on the same graph with the dynamic equilibrium model here, but the original forecast of mine was made as part of my effort to come up with way to forecast recessions. With what I know now, I wouldn't have made this forecast — the tolerance for positing a recession was too low and would have choked on earlier data if used in this model.

Here is the graph with the latest unemployment data on it:


The gray forecast assumed a recession was happening in the next few quarters, while the red dynamic equilibrium forecast assumes no shocks. The former is resoundingly rejected. Now how about a statement from the FRB SF rejecting their previous forecast?

Instead of rejecting their previous forecasts, the FRB SF has continually been updating their forecasts over time as the future they predict fails to materialize (which I noted in this post making the point that forecast instability is a sign you have the wrong model, and it's the point I am making with this gallery). I've also added the FOMC's forecast to the series of head to heads:


The FOMC does basically the same thing, which I've emphasized by adding in their December 2014 forecast in purple.

Update

The FRB SF has yet another forecast update, which I have added to the graph above:


This kind of forecast updating would be fine if it a) was stable, and b) had a longer period of success relative to the forecast length. If a forecast is made for a couple years in the future but only works for a couple of months, you should stop forecasting longer than a couple of months.

The thing is that if there is a recession that starts in the next couple years, the latest forecast will be seen as correct despite the fact that nearly every prior forecast was wrong over this length of time. It is unscientific. Much like the perpetual pessimists always forecasting a recession being seen by some as being successful when a recession happens (Hello, Steve Keen!), it is a failure of Feynman's "leaning over backwards" to reject your own theories and models.

Thursday, October 5, 2017

The price mechanism as information bottleneck


I've been reading and writing about the "information bottleneck" lately (e.g. this paper, or e.g. this post) focusing on how it might relate to the price mechanism. In the post, I argued that the price mechanism works by destroying information instead of aggregating or communicating it.

I thought this might be a neat example to try out Mathematica's Classify machine learning function. So I set up some training data on a simple system with three agents (1, 2, 3), a price that could take on three values (1, 2, 3) for an allocation of three units of one good. Of course, one one hand all the threes make this confusing — but on the other hand this website is free.

There are ten different possible allocations of three widgets across three agents which I designate by a list of three numbers: e.g. {1, 2, 0}, {0, 0, 3}, {1, 1, 1}, etc. Each allocation is then related to a price in the training data; here's a graphical representation of that (noisy) training data (that we'll later relate to the information bottleneck):


The prices are on the right, and the various possible allocations are on the left, with the arrows showing when a price was related to a particular allocation (sometimes multiple times, and sometimes an allocation was related to two different prices). Running c = Classify[trainingData], we get a function c[.] that maps an allocation to a price p:

c[{3, 0, 0}] = 1
c[{2, 1, 0}] = 2

If we look at the various allocations related to each price (and weight them by their probabilities), we can get an idea of a "typical" allocation that yields each price:


Each price is represented by a different color. The horizontal line at 10% represents the probability of any particular allocation if we had a uniform distribution over the different allocations (since there are 10 of them). It's also the result when the machine learning algorithm fails, essentially choosing the least informative prior.

We can see when the price is p = 1, then agent 1 ends up with more of the stock of widgets. When p = 2, the distribution is more uniform (it was set up as the "equilibrium price" in the training data). Although each agent in this particular setup is a consumer, we can think of 1 as the "consumer" and 3 as the "producer". If the price is too high, agent 3 ends up with more of the goods on average (they don't sell); if the price is too low, agent 1 does (over-consumption).

we can look at the information entropy of these allocations, and it is indeed maximized for the equilibrium price p = 2 (by construction):


We have an information bottleneck where these three price values (1.6 bits) are destroying the irrelevant information and capturing relevant information about the opportunity set (3.3 bits, for a loss of 1.7 bits — more than half the information content) [1].

I borrowed this information bottleneck diagram from this paper:


In our case, $X$ is the allocation (state space), and $Y$ is the price. Our classify function c[state] represents $\hat{X}$ and $\hat{Y}$ is the output of that function. It was trained on the data (the diagram at the top of this post). Of course, Classify isn't really doing this with a Deep Neural Network (there's actually just one hidden layer with 8 nodes), but what I'm trying to illustrate here is the formal similarities between destroying information in the price mechanism and the information bottleneck.

We can envision the price mechanism as setting up a primitive neural network machine learning algorithm: the price functioning as an autoencoder of the state space information, destroying the irrelevant information in the information bottleneck, and then the flow of money reinforces the connection between neurons (i.e. exchages between agents).


We can add a second state space defining the demand for widgets (the state space above defines the supply). If these state spaces match up, then the supply and the demand will see the "equilibrium" price for the equilibrium allocation. Deviations on either side will will mean the market price will differ from the price derived from either the supply distribution or the demand distribution. Information will flow from supply to demand (or vice versa) via exchanges, and the price will change to represent the new state. This process will continue until the relevant information content of the supply distribution (captured via the bottleneck, with irrelevant information being destroyed) is equivalent to the information content of the demand distribution — i.e. information equilibrium.

If we take demand as constant (i.e. the real data we are trying to learn), this is identical to training a neural network with a Generative Adversarial Network (GAN) algorithm. Different supply distributions are created via exchanges and the price (the bottleneck) discriminates between them leading what should eventually be identical distributions on both sides when the price can no longer discriminate (i.e. is constant) between the supply distribution and the demand distribution.

Or at least that is how I am thinking about this at the moment. It is possible we need to look at the joint distribution of supply and demand as one big state space. More work to be done!

...

Footnotes:

[1] Additionally, I went through and did random trades among the agents (select two agents at random, and if one agent has more widgets than the other and the other has money at the price dictated by the future allocation — i.e. the allocation that would result from a trade — there's a trade). This eventually produces an equilibrium (an equilibrium price of 2 with a uniform allocation):


I want to eventually make the machine learning algorithm re-train on the new data that's produced from a transaction, which would likely reinforce some price probabilities and reduce others.


Sunday, October 1, 2017

The price mechanism and the information bottleneck

David Glasner has a nice post on "imperfect information" in economics. In it, he discusses how the idea of painting Hayek and Stiglitz as "polar opposites" generally gets it wrong, and that Hayek didn't think markets had "perfect information". What was interesting to me is that a significant number of the arguments with commenters and on Twitter that resulted from my Evonomics piece tried to make a similar point: that Hayek didn't say markets were always perfect. As I mention in my response, I never said that Hayek thought markets were perfect — quoting precisely a passage where Hayek says they're not perfect [1].

My contention is that not only aren't markets perfect, but even if they work they are not working in the way Hayek says they work when he looks at the case of functioning markets. I will also argue that the fact that neither a central planner nor a market can actually receive or transmit the information claimed to be flowing, making Hayek's argument against central planning simultaneously an argument against markets — if they function the way Hayek claims they function. However, I will conclude with a discussion on how the price mechanism may actually function by destroying information. 

Let's start with Glasner quoting Timothy Taylor quoting Hayek:
[The market is] a system of the utilization of knowledge which nobody can possess as a whole, which ... leads people to aim at the needs of people whom they do not know, make use of facilities about which they have no direct [knowledge]; all this condensed in abstract signals ...
Glasner responds to this (and the rest of the quoted section of Taylor's post):
Taylor, channeling Bowles, Kirman and Sethi, is here quoting from a passage in Hayek’s classic paper, “The Use of Knowledge in Society” in which he explained how markets accomplish automatically the task of transmitting and processing dispersed knowledge held by disparate agents who otherwise would have no way to communicate with each other to coordinate and reconcile their distinct plans into a coherent set of mutually consistent and interdependent actions, thereby achieving coincidentally a coherence and consistency that all decision-makers take for granted, but which none deliberately sought. The key point that Hayek was making is not so much that this “market order” is optimal in any static sense, but that if a central planner tried to replicate it, he would have to collect, process, and constantly update an impossibly huge quantity of [knowledge].
There is an issue where in economics the words "information" and "knowledge" are synonymous (just like the colloquial English definitions [2]) that gets in the way of talking about this in terms of information theory. Therefore I traded "information" for "knowledge" in the quotes above (emphasizing with brackets). Knowledge is meaningful, whereas information represents a measure of the size of an available state space (weighted by probability of occupation) regardless of whether a state selected from it is meaningful. The phrases "The speed of light is a constant" and "Groop, I implore thee, my foonting" are drawn from a state space of approximately the same amount of information (the latter actually requires more), but the former is more meaningful and represents more knowledge.

This measure of information was designed to understand how to build systems that enable you to transmit either message. I'm not trying to say that Claude Shannon's definition is "better" than the economics definition or anything — there's simply a technical meaning given to it in information theory because of a distinction that hasn't been necessary in economics. In defining it, Shannon had to emphasize "information must not be confused with meaning".

However, this semantic issue allows us to get a handle on the mathematical issue with Hayek's mechanism. There is no way for this "impossibly huge quantity of knowledge" to be condensed into a price (a single number) because the amount of information (e.g. the thousands of — including "expected" — production numbers [x1, x2, x3, ... ], where the "knowledge" of them represents a specific set [42, 6, 9, ... ]) is too great to be conveyed via that single number without an encoding scheme and drawing out the message over time. You could e.g. encode the numbers as Morse code and fluctuate the price over a few seconds, but the idea that there are messages like that in market prices is so laughable that we don't even need to discuss it. I'll continue use brackets to emphasize use of the technical distinction below.

Therefore one thing that market prices are not doing is "condensing" or "transmitting and processing" dispersed knowledge. Prices are incapable of carrying such an information load. The information is largely being destroyed rather than processed or compressed.

When Stiglitz and others talk about imperfect [knowledge], they are actually talking about the fact that the information has been destroyed. A price of a used car isn't going to allow me to glean enough information about the state of that car — especially if you place the desires of the human used car salesperson to get a good price for it. Where an "honest" salesperson might price the car below Blue Book value because it has been flood damaged, the buyer's imperfect [knowledge] of the flood damage means the salesperson would rationally try to get Blue Book value. However, even a sub-Blue Book price cannot communicate the information state of the accident history, transmission, engine, etc in addition to that flood damage.

There's already an [information] asymmetry between the available states the car could be in and the available states the price could take. There is the additional [knowledge] asymmetry made famous by Akerlof's The Market for Lemons on top of that.

But, you say, the price mechanism seems to function "as if" it is communicating information. I guess you could devise an effective theory where the state space information is actually really small (undifferentiated widgets that have some uniform production input). But that's basically just another way to describe the argument above: in order for the price to transmit dispersed knowledge, there mustn't be much knowledge to be transmitted. In a sense, this makes Hayek's argument against central planning a kind of straw man argument. Sure, a central planner can't collect and process all of this information, but the price mechanism can't do this either.

One of the reasons I belabor this particular point is because in trying to understand how information equilibrium relates to economics, I had to understand this myself. As I said in my "about me" blog post:
... I stumbled upon this paper by Fielitz and Borchardt and tried to apply the information transfer framework to what is essentially Hayek's description of the price mechanism. That didn't exactly work, but it did work if you thought about the problem differently.
The part that "didn't exactly work" was precisely Hayek's description of information being compressed into the price. You had to think about the problem differently: the price was a detector of information flow, but unlike a thermometer or a pressure gauge (that have a tiny interface in order to not influence what it is measuring) the price is maximally connected to the system. The massive amount of information required to specify an economy was actually flowing between the agents in the economy itself (i.e. the economic state space information), with the price representing only a small amount of information.

But if this is true, then we might ask: Since it frequently appears to work in practice, how could the price mechanism work when it does?

I think the answer currently is that we don't know. However, I am under the impression that research into machine learning may yield some insights into this problem. What is interesting is that the price not as receiver but rather as detector is reminiscent of a particular kind of machine learning algorithm called Generative Adversarial Networks (GANs). GANs are used to train neural nets. They start with essentially randomly generated data (the generative bit) which is then compared to the real data you want the neural net to learn. A "discriminator" (or "critic" in some similar methods) checks how well the generator's guesses match the real data. 


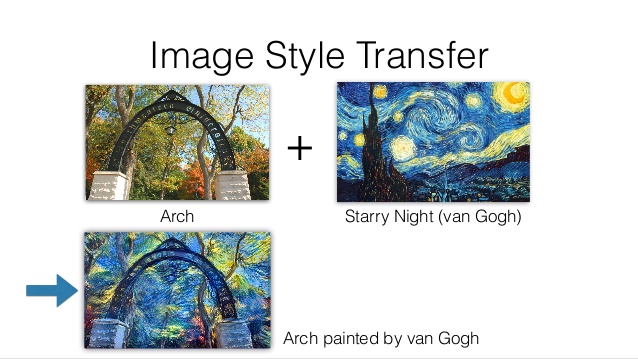
Imagine art students trying to copy the style of van Gogh, and the art teacher simply saying you're doing well or not. It is amazing that this can actually work to train a neural net to copy the style of van Gogh (pictured above). A simpler but similar situation is a game of "warmer/cooler" where someone is looking for an object and the person who knows where it is tells them if they are getting warmer (closer) or cooler (farther). In this case, it is not as counterintuitive that this should work. Much like how it is not as problematic for Hayek's price mechanism to operate with generic widgets, what we have in the case of a game of "warmer/cooler" is very low dimensional state space so the sequence of "warmer/cooler" measurements from the "discriminator" is much closer in information content to the actual state space. In the case of van Gogh style transfer, we have a massive state space. There is no way the sequence of art teacher comments could possibly come close to the amount of information required to specify a van Gogh-esque image in state space.

However, information must be flowing from the actual van Gogh (real data) to the generator because otherwise we wouldn't be able to generate the van Gogh-esque image. The insight here is that information flows from the real data to the generator, and the quantity of information flowing will be indicated by the differences between the different discriminator scores. A constant score indicates no information flow. A really big improvement in the score indicates a lot of information has flowed.

Again, we don't know exactly how this works for high dimensional state spaces, but a recent article in Quanta magazine discusses a possible insight. It's called the "information bottleneck". In the information bottleneck, a bunch of information about the state space in the "real data" that doesn't generalize is destroyed (e.g. forgetting irrelevant correlations), leaving only "relevant" information about the state space.

To bring this back to economics, what might be happening is that the price mechanism is providing the bottleneck by destroying information. Once this information is destroyed, what is left is only relevant information about the the economic state space. My private information about a stock isn't aggregated via the price mechanism, but rather is almost entirely obliterated [3] when the market is functioning.

With most of this private information being obliterated in the bottleneck, measurements of the information content of trades should actually be almost zero if this view is correct. It is interesting that Christopher Sims has found that only a few bits of information in interest rates seems to be used by economic agents, and other research shows that most traders seem to be "noise traders". Is the information bottleneck destroying the remaining information?

This is speculation at this stage; I'm just thinking out loud with this post. However the information bottleneck is an intriguing way to understand how the price mechanism can work despite a massive amount of information falling on the floor.

...

Footnotes:

[1] Hayek from The Use of Knowledge in Society:
Of course, these [price] adjustments are probably never "perfect" in the sense in which the economist conceives of them in his equilibrium analysis. But I fear that our theoretical habits of approaching the problem with the assumption of more or less perfect knowledge on the part of almost everyone has made us somewhat blind to the true function of the price mechanism and led us to apply rather misleading standards in judging its efficiency. The marvel is that in a case like that of a scarcity of one raw material, without an order being issued, without more than perhaps a handful of people knowing the cause, tens of thousands of people whose identity could not be ascertained by months of investigation, are made to use the material or its products more sparingly; i.e., they move in the right direction. This is enough of a marvel even if, in a constantly changing world, not all will hit it off so perfectly that their profit rates will always be maintained at the same constant or "normal" level.
[2] The definitions that come up from Google searching "define knowledge" and "define information":
knowledge: facts, information, and skills acquired by a person through experience or education; the theoretical or practical understanding of a subject.
information: facts provided or learned about something or someone.
The difference between these definitions is basically the inclusion of "skills". What's also interesting is that the second definition for information gets better:
information: what is conveyed or represented by a particular arrangement or sequence of things.
Although the information theory definition of information entropy depends on the state space of possibilities that particular arrangement was selected from.

[3] In fact, the cases where my information isn't obliterated but rather amplified may well be the causes of market failures and recessions. Instead of my fear that a stock price is going to fall being averaged away among the optimistic and pessimistic traders, it becomes amplified in a stock market crash. The information transfer framework labels this as "non-ideal information transfer" (a visualization using a demand curve as an example is here).

Friday, September 29, 2017

Checking in on an inflation forecast

I made a forecast of PCE inflation using the dynamic information equilibrium model described in this post at the beginning of the year, and so far the model is doing well — new monthly core PCE data came out this morning:


Thursday, September 28, 2017

A forecast validation bonanza

New NGDP numbers are out today for the US, so that means I have to check several forecasts for accuracy. I would like to lead with a model that I seem to have forgotten to update all year: dynamic equilibrium for the ratio of nominal output to total employed (i.e. nominal output per employed, as I write N/L):


This one is particularly good because the forecast was made near what the model saw as a turnaround point in N/L (similar to the case of Bitcoin below, also forecast near a turnaround point) saying we should expect a return towards the trend growth rate of N/L of 3.8% per annum. This return appears to be on track.

The forecast of NGDP using the information equilibrium (IE) monetary model (i.e. a single factor of production where money — in this case physical currency — is that factor of production) is also "on track":


The interesting part of this forecast is that the log-linear models are basically rejected.

In addition to NGDP, quarterly [core] PCE inflation was updated today. The NY Fed DSGE model forecast (as well as FOMC forecast) was for this data, and it's starting to do worse compared to the IE monetary model (now updated with monthly core PCE number as well):


*  *  *

I've also checked my forecast for the Bitcoin exchange rate using the dynamic equilibrium model (which needs to be checked often because of how fast it evolves — it's time scale is -2.6/y so it should fall by about 1/2 over a quarter). It is also going well:


Update + 2 hours

Also, the S&P 500: